
Scaling Real-Time Simulation Across Multiple CPU Cores
Modern simulation systems can provide dozens of processor cores, but additional cores do not automatically make a real-time model execute faster.
The workload must be divided into processes or threads that can run concurrently. Those tasks must then be assigned to processor resources without introducing excessive synchronization, memory contention, or interference from unrelated system activity.
For real-time simulation, the objective is also different from that of a general computing workload. The goal is not simply to complete more calculations per second. Every time-critical model and I/O operation must finish within its assigned deadline.
Effective multicore real-time simulation therefore requires intentional workload partitioning, processor assignment, isolation, and measurement.
Why Real-Time Simulations Need Multicore Processing
Simulation models continue to increase in size and complexity. A single test environment may include:
- Multiple plant and controller models
- Models operating at different sample rates
- High-channel-count physical I/O
- Communication-bus simulation
- Data recording
- Test scripting
- Visualization
- Fault injection
- Operator-in-the-loop components
- Models supplied by different engineering teams
Attempting to execute all these functions sequentially on one processor core can limit model size or force engineers to use a slower simulation rate.
Multiple cores provide an opportunity to run independent work concurrently. For example, two models without a direct same-cycle dependency may be able to execute at the same time on separate cores.
The practical benefit depends on how much of the workload can actually run in parallel.
More Cores Do Not Automatically Reduce Execution Time
A single-threaded model normally runs on one processor core at a time. Assigning it to a system with more cores does not divide its calculations automatically.
To use multiple cores, the simulation workload must contain separable units such as:
- Independent models
- Model subsystems generated as separate threads
- Different sample-rate groups
- Dedicated I/O processes
- Communication tasks
- Data-recording processes
- Visualization and support applications
Dependencies among those units determine which tasks can run simultaneously.
If Model B needs the current-cycle output of Model A, Model B may have to wait until Model A completes. Moving the two models to separate cores does not remove that dependency.
Parallel execution is most useful when tasks can operate independently for a meaningful portion of the simulation cycle.
Throughput Is Not the Primary Metric
General-purpose multicore applications are often evaluated by throughput: how much total work the system completes over time.
Real-time simulation is primarily constrained by deadlines.
Suppose four models must complete during a one-millisecond simulation period. Distributing them across four cores may reduce the overall completion time. However, the test still fails its timing requirement if one model occasionally finishes after the deadline.
Useful measurements include:
- Maximum execution time of each model or thread
- Completion time of the complete simulation frame
- Variation between frames
- Processor utilization by core
- Time spent waiting at synchronization points
- Frequency and duration of overruns
- Processing headroom under peak workload
- Interference from interrupts and operating-system activity
Average processor utilization can hide a task that occasionally exceeds its timing budget.
Partitioning a Simulation Workload
Workload partitioning determines which parts of the simulation execute independently.
Separate models
Models representing different subsystems can often run as separate processes. A vehicle simulation, for example, might separate the powertrain, vehicle dynamics, environment, and sensor models.
Whether they can run concurrently depends on their data dependencies and required execution order.
Separate rate groups
A multirate model may generate separate threads for its discrete sample rates. Faster and slower rate groups can then be scheduled according to their periods and, where appropriate, assigned to different processor cores.
As discussed in How Multirate Real-Time Simulation Works, engineers must pay particular attention to cycles in which several rates coincide.
Separate I/O processing
Dedicated I/O processes can prevent device-handling logic from becoming embedded in model execution. Synchronous I/O still needs to complete within the simulation frame, while asynchronous I/O can often operate outside the critical loop.
The distinction is covered in Synchronous vs. Asynchronous I/O in Real-Time Simulation.
Separate support applications
Logging, visualization, network services, and user interfaces should not compete unnecessarily with time-critical models. Moving them to noncritical cores can reduce interference, although their complete effect on memory, storage, and network resources still needs to be measured.
CPU Affinity and Core Assignment
CPU affinity restricts a process or thread to a selected processor core or set of cores.
Without an affinity policy, the operating system may move a task among available processors. Migration can introduce timing variation because the task may lose access to cached data and compete with different workloads after each move.
Assigning a time-critical model to a specific core provides a more stable execution environment and makes processor utilization easier to analyze.
A core-assignment plan might place:
| Processor resource | Illustrative workload |
| System core | Operating-system services, network traffic, and administrative processes |
| Simulation core 1 | Fast plant or control model |
| Simulation core 2 | Additional models or rate groups |
| Simulation core 3 | Time-critical I/O or another independent model |
| Support core | Logging, visualization, and asynchronous communication |
This is only an example. The appropriate layout depends on the number of cores, model dependencies, I/O architecture, interrupt sources, and required sample rates.
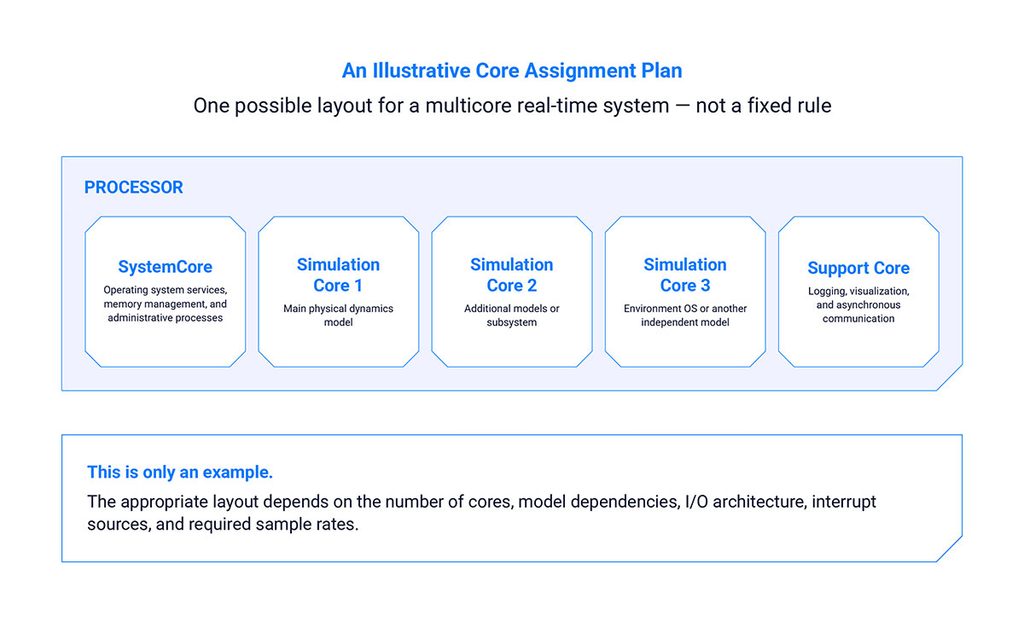
Figure 1. An illustrative core-assignment plan, the right layout depends on core count, dependencies, I/O architecture, and sample rates.
CPU affinity controls where a task is allowed to run. It does not by itself prevent other tasks from running on that core.
CPU Shielding and Workload Isolation
CPU shielding reserves selected cores for time-critical work by limiting unrelated operating-system activity on those processors.
A simulation core may need protection from:
- General application processes
- Background services
- Unrelated kernel work
- Network processing
- Storage activity
- Device interrupts
- Monitoring agents
- User-interface applications
Shielding reduces possible interference, but a complete isolation plan may also need to control interrupt routing and the placement of system services.
A shielded core can still experience contention through shared hardware resources such as caches, memory controllers, interconnects, and storage. Isolation must therefore be verified through measurement rather than assumed from the CPU assignment alone.
CPU Affinity and CPU Shielding Are Not the Same
The two techniques are complementary.
- CPU affinity defines where a particular task can execute.
- CPU shielding limits which other workloads can execute on the selected core.
Pinning a model to a busy core may make its timing more consistent but consistently poor. Shielding a core without assigning the correct simulation task to it also does not solve the workload-placement problem.
A deterministic configuration normally needs both controlled placement and controlled interference.
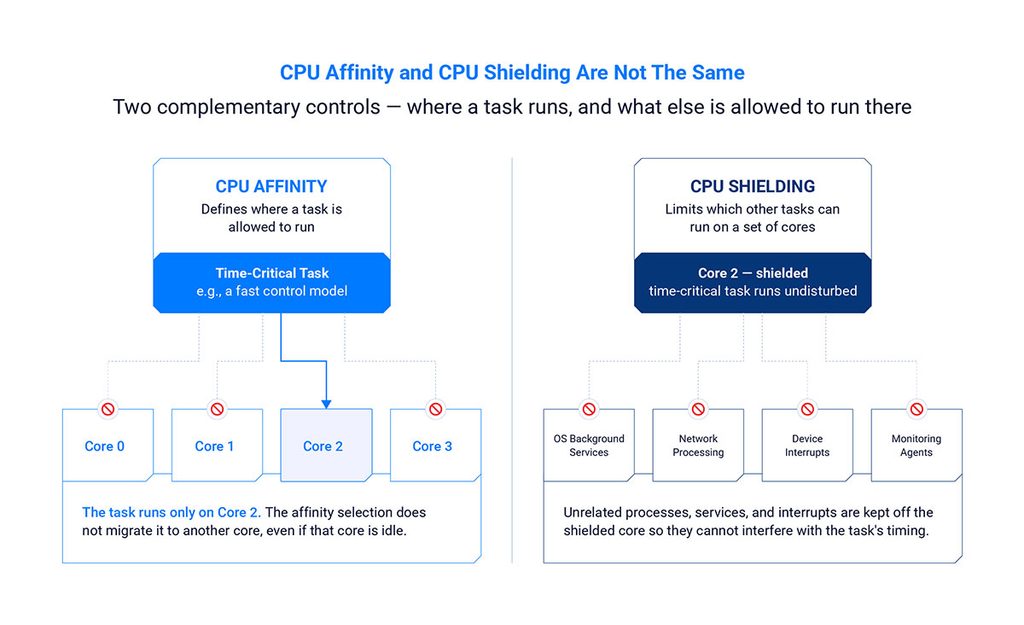
Figure 2. CPU affinity controls where a task runs; CPU shielding controls what else can run there. A deterministic setup needs both.
Synchronization Can Limit Multicore Scaling
Models running on different cores frequently need to exchange data or wait for a shared simulation boundary.
Synchronization may involve:
- Waiting for inputs to become available
- Coordinating the start of a simulation frame
- Enforcing execution order between dependent models
- Waiting for all models to complete before output processing
- Protecting shared data
- Transferring values between rate groups
- Coordinating distributed I/O
Every synchronization point can reduce the time saved through parallel execution.
For example, if three models finish quickly but a fourth model consistently takes much longer, the other cores may remain idle while waiting for the final model. The longest dependent path not the average across all cores—determines when the simulation can advance.
Locks and other shared-resource controls can create similar delays if several tasks compete for the same data structure.
The objective is not to eliminate all synchronization. It is to make dependencies explicit and avoid unnecessary serialization.
Shared Caches, Memory, and NUMA Effects
Processor cores do not operate in complete isolation. They may share caches, memory bandwidth, interconnects, and access to I/O devices.
Two models that perform well individually may interfere with each other when they run concurrently because both require substantial memory bandwidth or compete for shared cache capacity.
Large multisocket systems may also use non-uniform memory access, or NUMA. Memory located near one processor may take longer for a core on another processor to access.
Potential considerations include:
- Keeping a task and its frequently accessed data on the same NUMA node
- Avoiding unnecessary movement of tasks between processors
- Measuring memory bandwidth under the complete workload
- Watching for cache contention between neighboring cores
- Placing I/O processing near the hardware resources it uses
- Avoiding excessive cross-core sharing of frequently updated data
These effects are hardware- and workload-dependent. They should be measured on the intended target system.
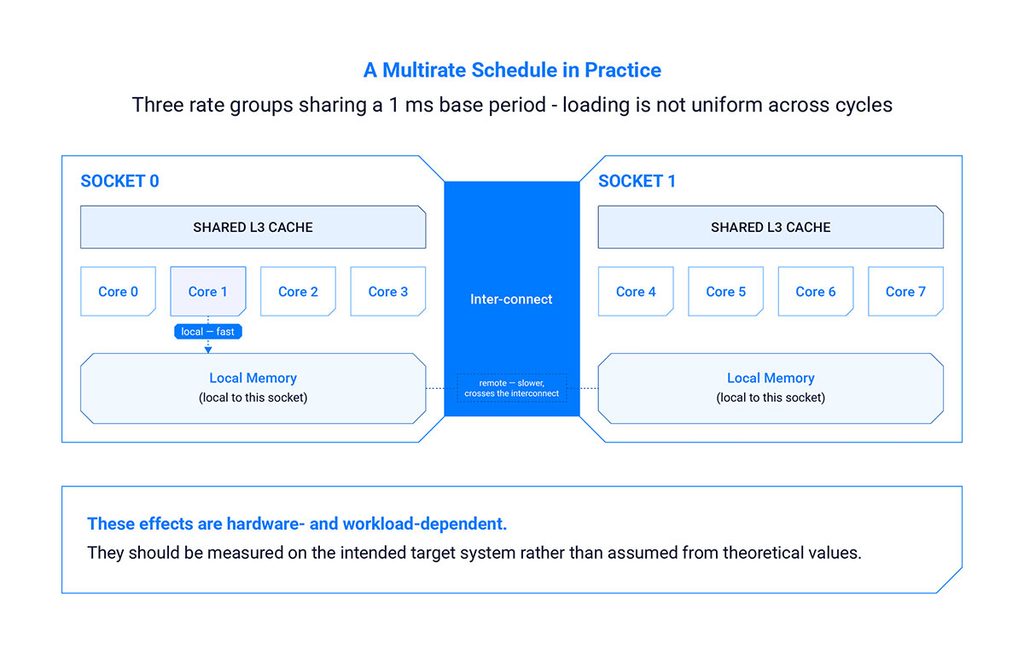
Figure 3. On multisocket systems, local memory access is fast; crossing the interconnect for remote memory is slower.
Logical Processors and Shared Core Resources
Some processors present multiple logical CPUs for each physical core. These logical processors share important execution resources.
A scheduler may display each logical processor as an available CPU, but two logical processors on the same physical core do not necessarily provide the isolation or capacity of two separate physical cores.
Time-critical tasks should not be assigned under the assumption that every logical processor represents an independent physical resource. If simultaneous multithreading is used, its effect on maximum execution time and jitter should be tested with the actual simulation workload.
Leave Processing Headroom
A real-time simulation should not be planned around continuous maximum processor utilization.
Execution time can change because of:
- Different model paths
- Fault conditions
- Increased bus traffic
- Additional logging
- Cache and memory effects
- Interrupt activity
- Growth in the model
- Added I/O channels
- Changes in generated code
- Future test requirements
Processing headroom allows the simulation to absorb bounded variation without missing its deadline. It also makes the test environment easier to extend.
There is no universal percentage of headroom that applies to every system. The required margin depends on the consequence of a missed deadline, the variability of the workload, and the evidence collected during timing analysis.
Measuring Whether Multicore Scaling Works
A new core assignment should be treated as a testable configuration change.
Engineers should compare:
- Complete frame time before and after repartitioning
- Maximum execution time for each task
- Per-core utilization
- Time spent waiting at synchronization points
- Overrun frequency
- Timing variation
- Memory and cache behavior
- Interrupt activity
- Performance with logging and visualization enabled
A change that lowers average utilization but increases worst-case timing variation may not be an improvement.
Testing should also include the most demanding rate alignment, I/O load, model path, and fault condition expected during operation.
Multicore Execution in SIMulation Workbench
SIMulation Workbench executes simulation models, I/O tasks, scripts, logging functions, and related processes within a scheduled real-time environment.
Models and model threads can be assigned to selected processor cores. This supports distributing independent models or discrete rate groups across the available processing resources.
SimWB runs on RedHawk Linux, which provides mechanisms for processor affinity, CPU shielding, interrupt control, and real-time scheduling. These controls allow engineering teams to define which resources are used for critical simulation work and which remain available for system and support functions.
The SimWB hybrid electric vehicle demonstration shows a multirate Simulink model in which separate rate threads can be assigned to processor cores. This illustrates how model structure, scheduling rate, and processor allocation work together.
The benefit still depends on the structure of the model and its dependencies. Assigning every process to a different core does not guarantee faster or more deterministic execution.
Questions to Ask When Planning a Multicore Simulation
Before assigning workloads, engineering teams should ask:
- Which models or threads can execute independently?
- Which tasks have same-cycle data dependencies?
- What is the longest dependent execution path?
- Which rate combinations create the highest workload?
- How much time is spent waiting at synchronization points?
- Which I/O tasks must remain in the real-time loop?
- Where are interrupts being processed?
- Which cores handle operating-system and support activity?
- Are logical processors sharing the same physical core?
- Is memory allocated near the processor using it?
- How much processing headroom remains?
- Does the configuration remain within its deadlines under peak load?
A processor map should be based on these answers rather than on core count alone.
Conclusion
Multicore processors provide the capacity to run larger and more complex real-time simulations, but useful scaling requires more than assigning tasks to additional cores.
Models and I/O workloads must be partitioned into units that can run concurrently. Their dependencies must be understood, time-critical processors must be protected from unrelated activity, and shared hardware resources must be considered.
Most importantly, the result must be measured using real-time criteria. Lower average CPU utilization is useful only if the complete simulation continues to meet its deadlines with adequate and understood timing headroom. For a broader discussion of multicore execution, multirate scheduling, I/O architecture, model integration, and test automation, download Designing Scalable, Deterministic X-in-the-Loop Simulation Environments.
Frequently Asked Questions
Does adding more CPU cores automatically make a simulation faster?
No. Additional cores help only when the workload can be divided into tasks that execute concurrently. A single-threaded model will generally continue to run on one core unless it is restructured or generated as multiple threads.
What is CPU affinity?
CPU affinity restricts a process or thread to a selected processor core or group of cores. It can prevent task migration and make workload placement more predictable.
What is CPU shielding?
CPU shielding limits unrelated operating-system and application activity on selected processor cores. It helps reserve those cores for time-critical simulation workloads.
Can one real-time model use multiple cores?
It depends on the model’s structure and generated code. A model may contain separate rate groups or computational components that can execute as independent threads. Dependencies between those components can limit parallel execution.
Should every available core be used for simulation models?
Not necessarily. Some processor resources may need to remain available for operating-system services, interrupts, asynchronous I/O, logging, networking, and user applications. The appropriate allocation must be tested on the complete system.
Is high CPU utilization desirable in a real-time simulation?
Not by itself. High utilization may indicate efficient use of the hardware, but insufficient timing headroom increases the risk of overruns when execution time varies or the test configuration grows.
Are logical processor threads equivalent to physical CPU cores?
No. Logical processors on the same physical core share execution resources. Their effect on worst-case timing and jitter should be evaluated before they are used for independent critical workloads.
Related Articles
-
White Paper: From Subsystem to Preflight A Progressive Hardware-in-the-Loop Validation Framework for Missile Development
White Paper: From Subsystem to Preflight A Progressive Hardware-in-the-Loop Validation Framework for Missile Development Discover a practical, three-stage approach to identifying subsystem, closed-loop, and mission-level integration risks before committing to flight testing.…
-
U.S. Treasury Assistant Secretary Chris Pilkerton Visits CCRT
Assistant Secretary Chris Pilkerton Visits Concurrent Real-Time Concurrent Real-Time was honored to welcome Chris Pilkerton, Assistant Secretary of the Treasury for Investment Security and Chair of the Committee on Foreign Investment in…
-
Real-Time Simulation for Aerospace and Defense: An Engineering Guide
Real-Time Simulation for Aerospace and Defense: An Engineering Guide Real-time simulation allows aerospace and defense teams to execute system models in synchronization with actual elapsed time. Unlike offline simulation, a real-time environment…