
HIL Test Automation: Scripting, Data Logging, and Playback
A hardware-in-the-loop test involves more than starting a simulation and observing the results.
Engineers may need to establish initial conditions, modify parameters, apply commands, inject faults, monitor limits, record signals, and return the system to a known state. When these actions are performed manually, small differences in timing or sequence can make test results difficult to compare.
HIL test automation converts that activity into a controlled and repeatable workflow. Scripting defines what happens during the test, data logging records how the system responds, and playback or rerun capabilities help engineers investigate failures.
The objective is not automation for its own sake. It is to create tests that can be repeated, reviewed, and understood.
Why Manual HIL Testing Becomes Difficult to Scale
Manual interaction is useful during early model development and exploratory testing. An engineer may adjust a parameter, force a signal, or observe a controller response through a graphical interface.
Problems arise when the same test must be performed repeatedly or by multiple people.
Manual procedures can vary because of:
- Differences in operator timing
- Missed setup steps
- Incorrect initial conditions
- Inconsistent parameter values
- Different signal-recording selections
- Unrecorded configuration changes
- Incomplete reset procedures
- Subjective pass/fail decisions
These variations make it harder to determine whether a changed result came from the device under test, the simulation model, the test procedure, or the operator.
Automation moves repeatable actions into a controlled test definition.
What Should an Automated HIL Test Control?
A useful automated test should define more than the sequence of inputs.
Depending on the application, it may need to control:
- Model and I/O configuration
- Initial conditions
- Parameter values
- Simulation start and stop
- Test duration
- Command sequences
- Fault insertion and removal
- Signal overrides
- Data-recording selections
- Limit monitoring
- Timeout behavior
- Pass/fail criteria
- Reset and cleanup
- Result-file naming and storage
The more completely these elements are defined, the easier it becomes to reproduce the test later.
A Typical Automated Test Sequence
An automated HIL test may follow a sequence like this:
| Stage | Example activity |
| Configure | Load the required models, mappings, scripts, and logging definition |
| Initialize | Apply known parameters and initial conditions |
| Verify readiness | Confirm that required devices and data values are valid |
| Start | Begin real-time execution and data recording |
| Stabilize | Wait for the simulated system to reach a defined state |
| Stimulate | Apply commands, disturbances, or operating conditions |
| Inject faults | Introduce defined sensor, actuator, communication, or system faults |
| Monitor | Check values, state changes, deadlines, and safety limits |
| Complete | Stop the test after the required condition or duration |
| Evaluate | Apply pass/fail logic and identify unexpected behavior |
| Preserve | Save results with the associated test configuration |
| Reset | Return models and hardware to a known condition |
Not every test requires every stage, but the sequence should be explicit.
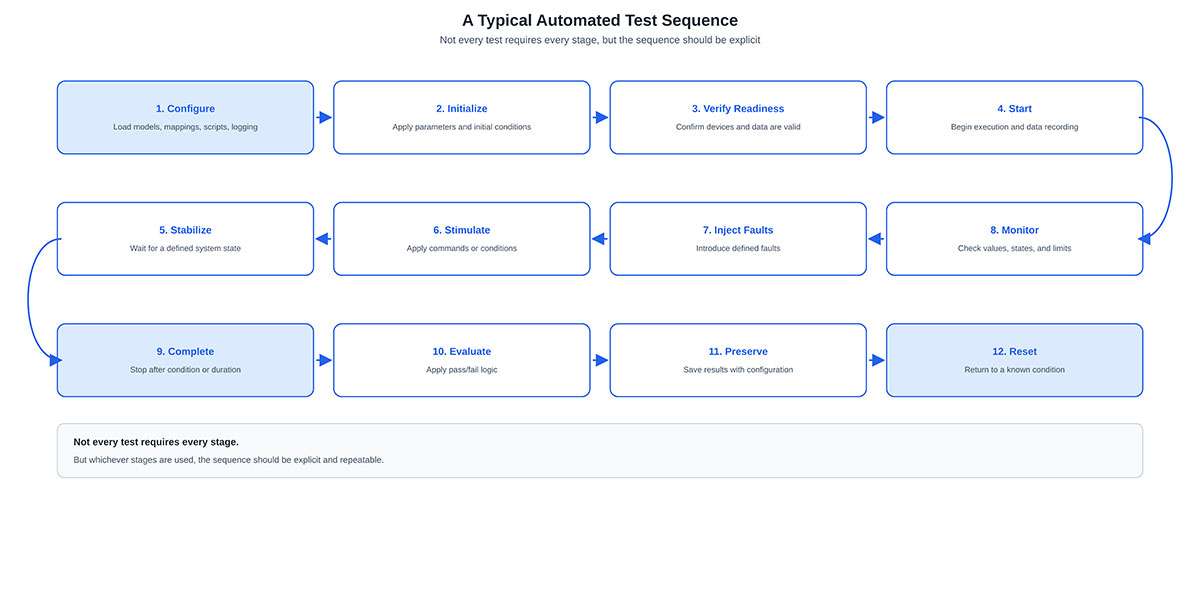
Figure 1. A typical automated HIL test sequence, from configuration through reset.
Script Actions Against Simulation Time or System State
Automated test steps can be initiated in several ways.
Time-based actions
A script may apply an input after a defined amount of simulation time:
- Start the simulation.
- Wait five seconds.
- Change a command value.
- Hold the condition for two seconds.
- Restore the original value.
Time-based sequences are straightforward, but they assume the system reaches the expected state within the allotted time.
State-based actions
A script can instead wait for a defined condition:
- Wait until engine speed reaches a threshold.
- Confirm that a controller enters a particular mode.
- Apply the fault after stabilization.
- End the test when the recovery state is reached.
State-based tests can adapt to normal variation, but every wait condition needs a timeout. Without one, an unexpected system state can cause the script to wait indefinitely.
Event-based actions
A test may respond to a device message, discrete transition, limit violation, or another observable event.
The script should record which event caused the action and when it occurred relative to simulation time.
A robust automated test frequently combines all three methods.
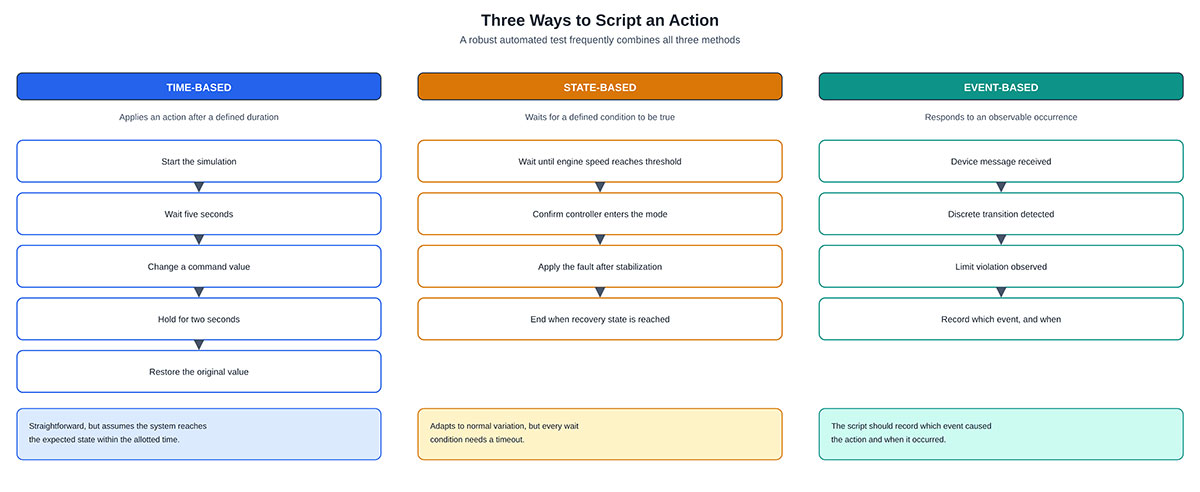
Figure 2. Scripted actions can trigger on time, on a system state, or on an observable event.
Use Explicit Initial Conditions
A repeatable test must begin from a known state.
Relevant initial conditions may include:
- Model states
- Parameter values
- Environmental conditions
- Simulation variables
- Controller mode
- I/O defaults
- Communication-bus state
- Fault status
- Data-recorder settings
Restarting a simulation process does not necessarily guarantee that every connected component has returned to its intended starting condition.
The automation should verify readiness before beginning the test. If a required value is invalid or a device has not reset, the script should stop with a clear error rather than continue with an unknown configuration.
Separate Test Logic from Model Logic
Test procedures should generally remain separate from the models being tested.
Embedding the complete test sequence in a simulation model creates unnecessary coupling. Changing a test condition may then require modifying and rebuilding the model even though the simulated behavior has not changed.
A separate scripting layer allows engineers to:
- Reuse a model across different tests
- Maintain multiple scenarios without duplicating the model
- Review test procedures independently
- Change commands and fault sequences without rebuilding model code
- Preserve a clearer boundary between simulated behavior and test control
This follows the same principle described in Why HIL Simulation Models Should Be Independent of the I/O Configuration: components that change for different reasons should not be unnecessarily embedded in one another.
Automating Fault Injection
HIL testing is particularly useful for evaluating conditions that would be difficult, unsafe, or expensive to create with the complete physical system.
Automated fault scenarios may include:
- Sensor values outside their normal range
- Frozen or drifting sensor signals
- Intermittent inputs
- Actuator failures
- Communication delays
- Dropped or corrupted messages
- Power or mode transitions
- Invalid status flags
- Environmental extremes
- Multiple simultaneous failures
The script should define:
- When the fault becomes active
- Which signals or interfaces are affected
- How the fault is represented
- How long it remains active
- Whether it clears automatically
- The expected response
- The conditions that terminate the test
Fault cleanup is important. A test that ends unexpectedly should not leave an override or injected failure active for the next run.
Logging the Right Data
Automated testing depends on recorded evidence. However, logging every available signal is not always practical or useful.
A logging definition should identify:
- Signals needed to determine pass or failure
- Inputs applied by the test
- Relevant model states
- Outputs from the device under test
- Fault status
- Data-validity indicators
- Scheduler or overrun information
- Values needed for later diagnosis
- Units and scaling
- Required recording rate
The selected rate matters. A signal recorded too slowly may miss short events, while recording every signal at the fastest simulation rate can generate unnecessary data and consume processing, storage, or network resources.
Logging should be tested as part of the complete real-time configuration. It should not be assumed to have no effect on timing.
Preserve Context with the Results
A data file without its configuration provides an incomplete test record.
Results should be associated with:
- Test-script version
- Model versions
- I/O mappings
- Initial conditions
- Parameter set
- Scheduler configuration
- Hardware configuration
- Software and driver versions
- Logging definition
- Date and test operator or automation process
- Device-under-test identifier
- Test outcome
This context allows an engineer to determine exactly what was running when the data was produced.
It also supports meaningful comparison between test runs. Two data sets should not be treated as equivalent if their model, hardware, mapping, or parameter configurations differ.
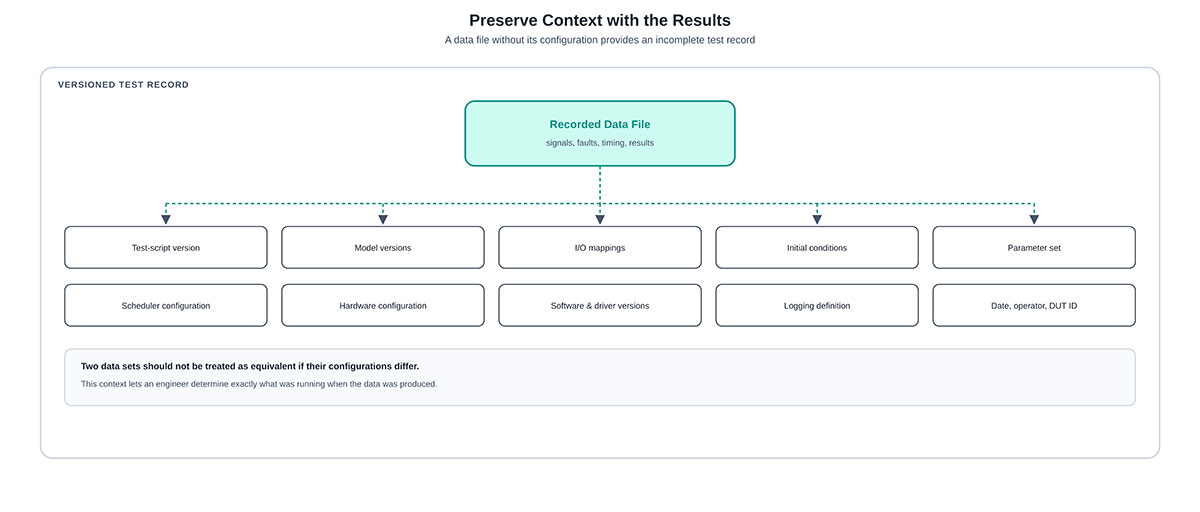
Figure 3. A recorded data file is only useful alongside the configuration that produced it.
Defining Pass and Fail Criteria
Automated execution does not necessarily provide automated evaluation.
A test can run the same sequence repeatedly while still requiring an engineer to inspect plots manually. For regression testing, it is often useful to define machine-evaluable criteria.
Examples include:
- A value must remain within a defined range.
- A response must begin within a specified interval.
- Overshoot must remain below a limit.
- The controller must enter the expected state.
- No simulation deadline may be missed.
- A fault must be detected and reported.
- The system must recover within a defined time.
- A message sequence must contain the expected status transitions.
Pass/fail criteria should include tolerances. Exact equality is often inappropriate for floating-point values, measured signals, and physical hardware.
The result should report not only that a limit failed but also which value, time, condition, and expected range caused the failure.
Playback, Rerun, and Data Review Are Different
These terms are sometimes used interchangeably, but they represent different diagnostic methods.
Data review
The recorded signals are plotted or analyzed after the test. The models and hardware do not execute again.
This is useful for investigating relationships among commands, states, outputs, faults, and timing events.
Scripted rerun
The same test configuration and script are executed again against the models and device under test.
A rerun tests repeatability, but connected physical hardware and external systems may not respond identically.
Simulation playback
Recorded data is replayed through a simulation or visualization workflow. Depending on the platform and configuration, playback can reproduce selected recorded values, allow frame-by-frame inspection, or provide inputs for further analysis.
Playback is useful for investigating a prior event without requiring every original component to be active. It does not always reproduce the complete closed-loop behavior of the original test.
Engineers should document which method is being used and what conclusions it can support.
Using Playback to Investigate Failures
When an automated test fails, playback and recorded data can help answer:
- Which signal first departed from expected behavior?
- Did the test apply the intended command?
- Was the device input late or missing?
- Did the model enter an unexpected state?
- Was the fault introduced at the correct time?
- Did the simulation experience an overrun?
- Was an asynchronous message delayed?
- Did a limit failure result from the test or the response?
Frame-by-frame inspection is especially useful when several events occur within a short interval.
Playback should be combined with configuration records. Replaying signal data without knowing the model, I/O, and test versions can lead to incorrect conclusions.
Automation Does Not Guarantee Determinism
A scripted test is more repeatable than a manual sequence, but scripting alone does not guarantee deterministic execution.
The simulation can still experience:
- Deadline overruns
- Timing jitter
- I/O delays
- Processor interference
- Queue overflows
- Logging contention
- Unexpected model execution paths
As explained in Why Deterministic Timing Matters in Real-Time Simulation, timing is part of the test result.
Automated tests should monitor timing health and record overruns or other scheduling violations alongside functional data. A functional pass may not be trustworthy if the simulation missed its required deadlines.
Designing Maintainable Test Scripts
Test automation can become difficult to manage if scripts grow without structure.
Useful practices include:
- Use descriptive names for tests and variables.
- Separate common setup and cleanup functions.
- Avoid unexplained numeric constants.
- Define timeouts for every wait condition.
- Record major test-state transitions.
- Stop safely when prerequisites are not met.
- Restore overrides and faults during cleanup.
- Keep pass/fail limits close to their requirement references.
- Version-control scripts and related configurations.
- Use reusable functions for repeated actions.
- Report failures with enough context for diagnosis.
A test script should be understandable to an engineer who did not write it.
HIL Test Automation in SIMulation Workbench
SIMulation Workbench includes scripting, programmatic control, real-time data recording, and simulation playback capabilities.
SimWB’s scripting environment can access simulation data and control test execution. The PYToolkit provides a Python-based interface for manipulating tests and interacting with simulation values from external automation workflows.
Test sessions can preserve run-specific settings such as initial conditions, scheduler configuration, overrun limits, and data-logging behavior. Models, scripts, I/O mappings, and RTDB definitions can be combined into a repeatable test configuration.
The SimWB Data Recorder logs selected real-time database values during execution. Recorded data can include engineering and hardware representations where configured. Playback and analysis tools allow engineers to review recorded tests and inspect simulation behavior over time.
These capabilities provide the mechanisms for automation, but engineering teams still need to define the test sequence, expected results, timing limits, configuration-control practices, and diagnostic data required for each application.
HIL Test Automation Checklist
Before relying on an automated test, confirm:
- The starting configuration is identified.
- Models and I/O mappings are versioned.
- Initial conditions are explicit.
- Required devices are checked before execution.
- Every wait condition has a timeout.
- Faults and overrides are cleared during cleanup.
- Applied commands are recorded.
- Functional pass/fail criteria are defined.
- Timing violations are treated as test events.
- Data-recording rates are appropriate.
- Logging does not disrupt real-time execution.
- Results preserve the associated configuration.
- The test can be rerun from its recorded definition.
- Failure messages identify the relevant signal and condition.
- Playback limitations are understood.
Conclusion
HIL test automation is most valuable when it makes a test repeatable and diagnosable.
Scripting controls the procedure. Data logging records the response. Pass/fail logic evaluates requirements. Playback and rerun capabilities help engineers investigate unexpected behavior.
The quality of the result depends on more than the automation interface. Initial conditions, configuration versions, timing health, data selection, cleanup behavior, and evaluation criteria must all be controlled. For a broader discussion of test automation, model integration, deterministic scheduling, I/O architecture, and multicore execution, download Designing Scalable, Deterministic X-in-the-Loop Simulation Environments.
Frequently Asked Questions
What is HIL test automation?
HIL test automation uses scripts or programmatic interfaces to configure, execute, monitor, and evaluate hardware-in-the-loop tests with less manual intervention.
What should an automated HIL test record?
It should record the applied inputs, relevant model states, device-under-test responses, fault status, timing health, and the configuration needed to reproduce the run.
Is simulation playback the same as rerunning a test?
No. A rerun executes the test again against active models and hardware. Playback uses previously recorded data for review or controlled reproduction within the capabilities of the platform.
Can HIL tests be evaluated automatically?
Yes. Scripts or external analysis tools can apply defined limits, timing requirements, state-transition rules, and other pass/fail criteria. Appropriate tolerances and diagnostic information should be included.
Does test automation eliminate the need for engineers?
No. Engineers still define the test conditions, expected behavior, tolerances, safety limits, and interpretation of failures. Automation makes consistent execution and evidence collection easier.
Does Windows development eliminate the need for access to the HIL target?
No. The target is still required for physical I/O integration, deterministic timing analysis, processor allocation, complete workload testing, and closed-loop validation.
Why separate the model from the target I/O configuration?
Separation allows the model to use consistent engineering variables during Windows development and connect to physical channels through target-specific mappings after deployment.
Related Articles
-
White Paper: From Subsystem to Preflight A Progressive Hardware-in-the-Loop Validation Framework for Missile Development
White Paper: From Subsystem to Preflight A Progressive Hardware-in-the-Loop Validation Framework for Missile Development Discover a practical, three-stage approach to identifying subsystem, closed-loop, and mission-level integration risks before committing to flight testing.…
-
U.S. Treasury Assistant Secretary Chris Pilkerton Visits CCRT
Assistant Secretary Chris Pilkerton Visits Concurrent Real-Time Concurrent Real-Time was honored to welcome Chris Pilkerton, Assistant Secretary of the Treasury for Investment Security and Chair of the Committee on Foreign Investment in…
-
Real-Time Simulation for Aerospace and Defense: An Engineering Guide
Real-Time Simulation for Aerospace and Defense: An Engineering Guide Real-time simulation allows aerospace and defense teams to execute system models in synchronization with actual elapsed time. Unlike offline simulation, a real-time environment…