
Event Tracing in Real-Time Systems: What Engineers Need to Know
When a real-time system behaves unexpectedly, the issue is rarely obvious.
- A task runs late but only sometimes.
- A response is delayed but not consistently.
- A system becomes unstable but only under specific conditions.
These are not problems you can easily isolate with breakpoints or logs.
They are timing problems and timing problems require visibility into how the system behaves over time.
This is where event tracing becomes essential.
What Event Tracing Actually Shows
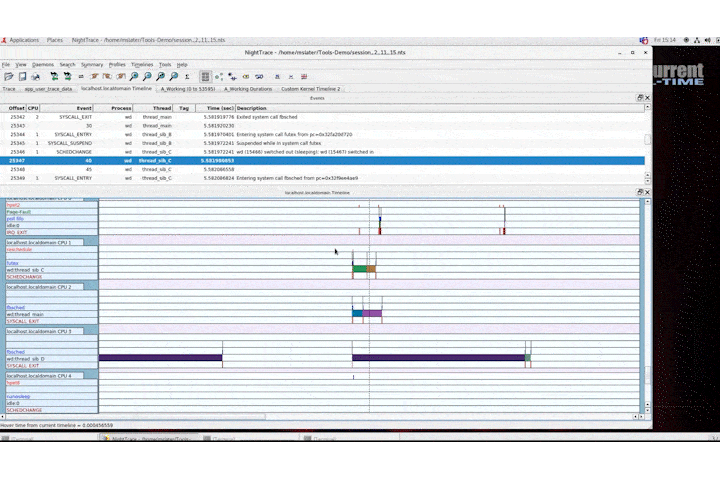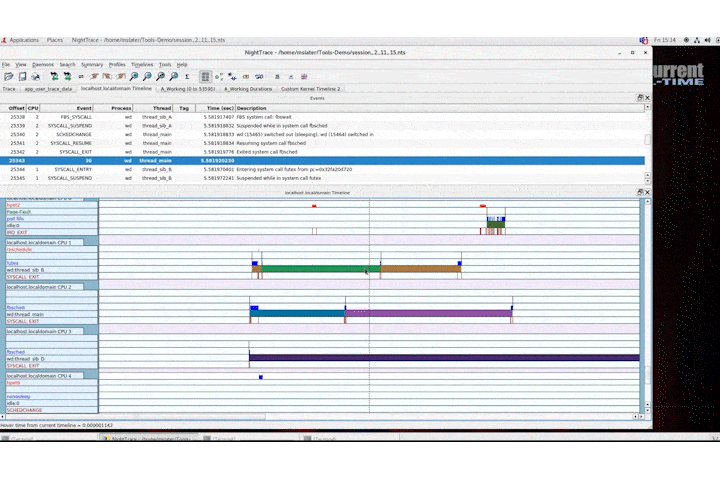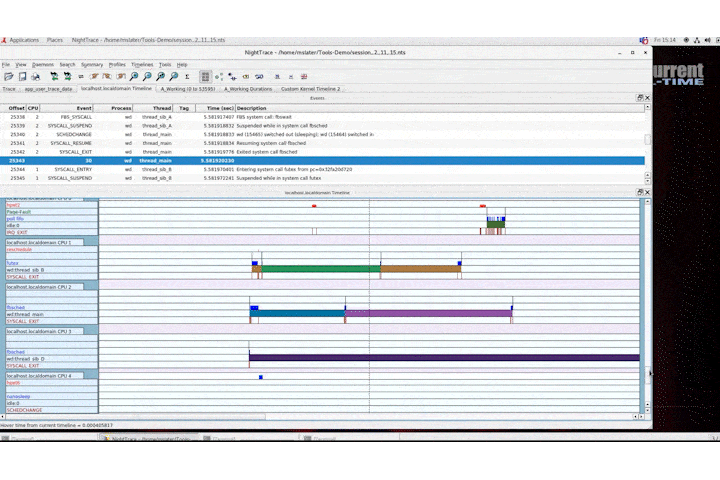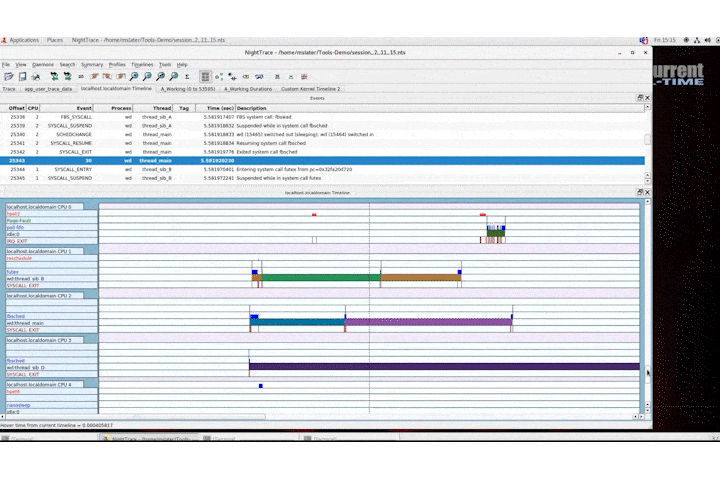
At a basic level, event tracing records system activity as a sequence of time-stamped events.
Instead of asking: “What is the system doing right now?”
Event tracing answers:
“What happened, in what order, and how long did each step take?”
A typical trace might include:
- task scheduling events
- interrupts and their handling
- system calls
- application-defined markers
The result is a timeline that reflects how the system actually executed.
Why Timing Problems Are Hard to Diagnose
In real-time systems, many issues are not caused by incorrect logic, but by when things happen.
For example:
- a control loop executes slightly later than expected
- an interrupt is delayed under load
- two tasks contend for the same resource
These issues are often tied to:
- jitter in real-time systems
- variability in interrupt latency
- interactions between concurrent processes
Without a timeline view, these behaviors are difficult to see and even harder to reproduce.
What This Looks Like in Practice
Consider a system where a control task should execute every 5 ms.
In simulation, everything appears stable.
With event tracing, you might see:
Expected:
Task runs at 5ms intervals
Actual:
5ms → 5ms → 7ms → 4ms → 6ms
Individually, these variations may seem small.
But over time, they can lead to:
- control instability
- synchronization issues
- degraded system performance
This is exactly the type of behavior event tracing is designed to reveal.

Key Capabilities of Event Tracing
Time-Stamped System Visibility
Every event is recorded with precise timing information, allowing engineers to measure:
- execution duration
- delays between events
- system response time
Cross-System Correlation
Event tracing allows you to correlate activity across:
- multiple processes
- multiple threads
- multiple CPU cores
This is critical in modern real-time systems where behavior depends on interactions across the system.
Reproducible Analysis
Unlike live debugging, event traces can be recorded and reviewed multiple times.
This makes it easier to:
- share results with other team members
- analyze complex issues
- compare system behavior across runs
Event Tracing vs Logging
It’s common to use logging when debugging systems, but logging and event tracing serve different purposes.
| Logging | Event Tracing |
| Captures specific messages | Captures system-wide activity |
| Limited timing precision | High-resolution time stamps |
| Developer-defined output | High-resolution time stamps |
| Often intrusive | High-resolution time stamps |
Logging can help identify where something failed and Event tracing helps explain why and when it failed.
Maintaining Accuracy During Tracing
To be useful, event tracing must not significantly affect system behavior.
If tracing introduces:
- additional latency
- scheduling delays
- resource contention
then the data may no longer reflect actual system performance.
This is why tracing tools are designed to operate with minimal intrusion, particularly in systems built on deterministic computing principles.
Event Tracing in HIL and Validation Environments
Event tracing is especially valuable in:
- hardware-in-the-loop (HIL) simulation
- integration testing
- system performance analysis
In these environments, engineers need to validate not just functionality, but:
- timing behavior
- system interaction
- response consistency
Event tracing provides the visibility needed to evaluate these factors accurately.
The Role of the Platform
Effective event tracing depends on the underlying system.
Platforms such as real-time Linux environments provide:
- predictable scheduling behavior
- low and consistent latency
- support for high-resolution timing
This ensures that trace data reflects system behavior rather than variability introduced by the platform.
Supporting Event Tracing with NightStar Tools
NightStar Tools include event tracing capabilities designed specifically for real-time systems.
Using tools such as NightTrace, engineers can:
- capture kernel and application events
- analyze system behavior over time
- correlate activity across processes and threads
- visualize timing relationships
These tools are designed to operate with minimal overhead, allowing accurate observation of system behavior without disrupting execution.
From Data to Insight
Event tracing produces a large amount of data. The value comes from understanding patterns within that data.
Key questions to ask:
- Where do delays occur?
- Are timing variations consistent or random?
- How do events relate across the system?
- What changes under load?
By answering these questions, engineers can move from observation to root cause analysis.
Real-time systems are defined not just by what they do, but by when they do it.
Event tracing provides the visibility needed to understand system behavior over time, making it possible to identify issues that are otherwise difficult to detect.
Combined with deterministic platforms and non-intrusive debugging techniques, event tracing is a critical tool for building and validating reliable real-time systems.
Related Articles
-

Preserving Legacy Real-Time Applications Through Virtualization
Preserving Legacy Real-Time Applications Through Virtualization Real-time applications often remain in service much longer than the hardware on which they were originally developed. Test systems, industrial controls, simulation environments, and data-acquisition platforms…
-

Native Real-Time Linux vs. Real-Time Virtualization: Which Architecture Fits Your Application?
Native Real-Time Linux vs. Real-Time Virtualization: Which Architecture Fits Your Application? Virtualization is now common in enterprise computing, but timing-sensitive systems introduce requirements that conventional IT workloads do not share. An application may…
-

How CPU Shielding, NUMA, and Interrupt Affinity Affect Real-Time Virtual Machines
How CPU Shielding, NUMA, and Interrupt Affinity Affect Real-Time Virtual Machines Running a real-time operating system inside a virtual machine does not automatically create a deterministic environment. The virtual machine still depends…